[Operational Guide #43] How to Build a Multi-Channel Social Media Auto-Poster for Medium, LinkedIn, and Twitter in Python
Operational Abstract
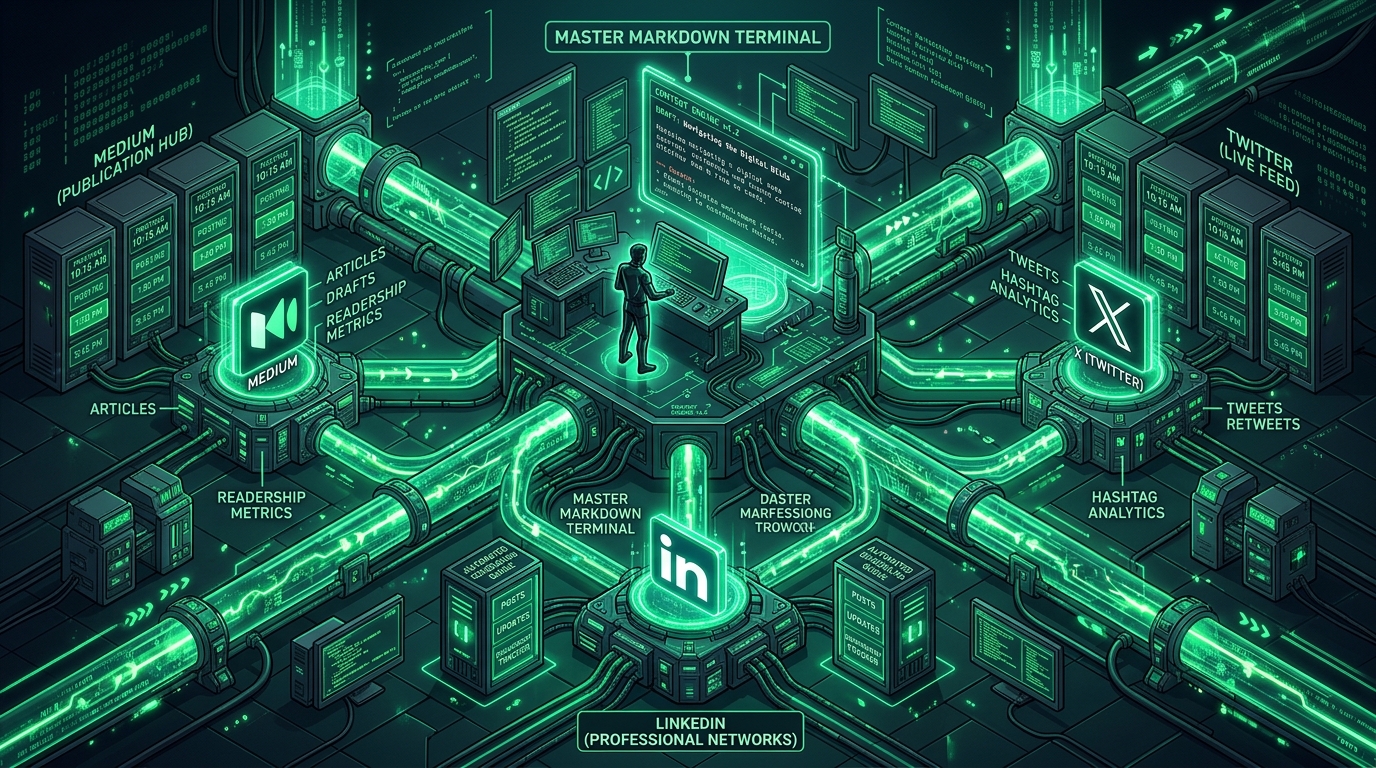
Crafting high-density technical publications requires immense cognitive capital. However, manually copying, reformatting, chunking, and cross-posting an article across Medium, LinkedIn, and Twitter/X squanders valuable hours and creates platform fragmentation. This operational guide details a production-grade Python syndication daemon that ingests a single master Markdown document, parses metadata frontmatter, auto-formats long-form canonical HTML for the Medium REST API, adapts concise business summaries for the LinkedIn Share API, splits core takeaways into numbered thread chunks for Twitter/X API v2, and tracks engagement with tagged UTM parameters in a persistent local ledger.
01. Operational Abstract: Eliminating Platform Fragmentation for Technical Authors
In modern digital commerce, distribution is leverage. An elite engineering essay or algorithmic financial analysis published exclusively on a self-hosted blog reaches only existing direct traffic. To maximize discovery, the author must syndicate the core ideas across high-authority third-party networks: Medium for search authority and SEO canonical backlinks, LinkedIn for enterprise B2B decision-makers, and Twitter/X for viral tech communities.
Yet, manually logging into three separate browser dashboards, copying text, re-uploading images, fixing broken markdown headers, and pasting hashtags is a soul-crushing chore. Over time, the administrative overhead leads to erratic publishing schedules and wasted intellectual property.
By automating this entire pipeline into a single local command—python auto_syndicate.py post.md—the sovereign operator writes once, executes once, and achieves immediate omnipresence across the global digital ecosystem.
02. Architecture: Single Master Markdown Ingest, Platform Adapters, Scheduled Dispatcher
Each publishing channel possesses distinct structural rules, formatting capabilities, and audience expectations. A naive cross-poster that dumps identical 3,000-word blocks into Twitter or pastes unstyled markdown into LinkedIn fails immediately. The architecture enforces decoupled platform adapters that transform a master Markdown source into native platform payloads:
| Target Channel | Payload Format | Character / Size Limit | Key Architectural Adapter Role |
|---|---|---|---|
| Medium API | Clean Semantic HTML | Unlimited Body Text | Injects canonicalUrl to protect self-hosted Google rank; sets tags |
| LinkedIn REST API | Clean Text + External Link Card | 3,000 Characters Max | Extracts 3-bullet executive summary + calls-to-action + hashtags |
| Twitter / X API v2 | Thread of Chunks (Replies) | 280 Characters per Tweet | Intelligent sentence-boundary chunker with (1/N) pagination |
A persistent local SQLite database logs successful publication IDs, timestamps, and canonical URLs, preventing accidental duplicate cross-posts.
03. Environment Setup: Dependencies, OAuth 2.0 Credentials, and Environment Keys
To initialize the multi-channel syndication daemon, install the required HTTP networking, markdown parsing, and Twitter SDK libraries:
# Create and activate Python virtual environment
python -m venv venv_social_poster
source venv_social_poster/bin/activate  # On Windows: .\venv_social_poster\Scripts\activate

# Install requests, markdown parser, tweepy, and python-dotenv
pip install requests tweepy python-frontmatter markdown python-dotenv
Configure your .env file with API access keys for Medium, LinkedIn, and Twitter/X Developer portals:
# Medium Integration (Integration Token from Settings -> Security)
MEDIUM_INTEGRATION_TOKEN=2a8f...your_medium_token
MEDIUM_AUTHOR_ID=19482...your_author_id

# LinkedIn OAuth 2.0 (Community Management / Share on LinkedIn)
LINKEDIN_ACCESS_TOKEN=AQX...your_linkedin_token
LINKEDIN_PERSON_URN=urn:li:person:AbCdEf1234

# Twitter/X API v2 (Developer Portal -> Keys and Tokens)
TWITTER_CONSUMER_KEY=AbC...
TWITTER_CONSUMER_SECRET=XyZ...
TWITTER_ACCESS_TOKEN=123...
TWITTER_ACCESS_SECRET=456...
TWITTER_BEARER_TOKEN=AAAAAAAAAAAAAAAAAAAAA...
04. Step 1: Parsing YAML Frontmatter & Markdown Content Structure
The input deliverable is a standardized Markdown file containing structured YAML frontmatter at the top. The engine uses python-frontmatter to extract the post title, canonical link, tags, and summary blurb while retaining the raw body markdown for subsequent compilation:
---
title: "The Zero-Knowledge Accounting Revolution for Solo Enterprises"
canonical_url: "https://www.bravoeconomy.com/2026/11/master-class-88-self-auditing-solo.html"
tags: ["FinTech", "Blockchain", "Python", "AutonomousBusiness"]
summary: "Why traditional annual audits are obsolete. How sovereign solo operators use Merkle tree proofs and double-entry streams to verify solvency in real time."
---

# Introduction to Continuous Accounting
Traditional corporate accounting is broken...
05. Step 2: Formatting Long-Form Canonical Posts for Medium API with Tags
When publishing to Medium, search engine duplicate content penalties are an existential risk. To guarantee that Google continues to attribute primary ranking authority to your self-hosted domain (e.g., bravoeconomy.com), the payload passed to POST https://api.medium.com/v1/users/{userId}/posts must explicitly declare the original publication link:
payload = {
    "title": post.metadata["title"],
    "contentFormat": "html",
    "content": compiled_html,
    "canonicalUrl": post.metadata["canonical_url"],
    "tags": post.metadata.get("tags", [])[:5],
    "publishStatus": "public"
}
06. Step 3: Formatting High-Engagement Business Updates for LinkedIn REST API
LinkedIn audiences prioritize strategic takeaways, clear white space, and professional tone over dense academic text. The LinkedIn adapter extracts the summary blurb, formats key operational takeaways into unicode bullet points (•), appends relevant corporate hashtags, and packages an external link card pointing back to the primary canonical article.
07. Step 4: Chunking Content into Threaded Tweets for Twitter/X API v2
The Twitter/X API enforces a strict 280-character limit per tweet. Rather than cutting sentences mid-word, our intelligent thread chunker splits the text at punctuation boundaries (periods, line breaks), prefixes each tweet with pagination counters (e.g., 1/5, 2/5), and chains each subsequent tweet as a direct reply (in_reply_to_tweet_id) to the preceding tweet ID.
08. Step 5: Full Production Python Pipeline: Syndication Engine & Persistent Ledger
Below is the complete, self-contained Python production engine. It parses the master Markdown document, invokes the respective channel adapters, publishes to Medium, LinkedIn, and Twitter/X via REST endpoints, and records audit receipts in an SQLite database.
import os
import re
import json
import sqlite3
import requests
import frontmatter
import markdown
import tweepy
from typing import List, Dict, Optional

class OmniChannelSyndicator:
    def __init__(self, db_path: str = "syndication_ledger.db"):
        self.db_path = db_path
        self.init_database()

        # Medium Credentials
        self.medium_token = os.getenv("MEDIUM_INTEGRATION_TOKEN")
        self.medium_author_id = os.getenv("MEDIUM_AUTHOR_ID")

        # LinkedIn Credentials
        self.linkedin_token = os.getenv("LINKEDIN_ACCESS_TOKEN")
        self.linkedin_urn = os.getenv("LINKEDIN_PERSON_URN")

        # Twitter Credentials
        self.twitter_client = None
        tw_consumer_key = os.getenv("TWITTER_CONSUMER_KEY")
        if tw_consumer_key:
            self.twitter_client = tweepy.Client(
                bearer_token=os.getenv("TWITTER_BEARER_TOKEN"),
                consumer_key=tw_consumer_key,
                consumer_secret=os.getenv("TWITTER_CONSUMER_SECRET"),
                access_token=os.getenv("TWITTER_ACCESS_TOKEN"),
                access_token_secret=os.getenv("TWITTER_ACCESS_SECRET")
            )

    def init_database(self):
        """Initializes persistent audit ledger for tracking published syndications."""
        with sqlite3.connect(self.db_path) as conn:
            cursor = conn.cursor()
            cursor.execute("""
                CREATE TABLE IF NOT EXISTS publications (
                    id INTEGER PRIMARY KEY AUTOINCREMENT,
                    file_path TEXT UNIQUE,
                    title TEXT,
                    medium_post_id TEXT,
                    linkedin_post_id TEXT,
                    twitter_thread_root TEXT,
                    published_at TIMESTAMP DEFAULT CURRENT_TIMESTAMP
                )
            """)
            conn.commit()

    def parse_markdown(self, file_path: str):
        """Parses frontmatter and content body from master Markdown."""
        if not os.path.exists(file_path):
            raise FileNotFoundError(f"Input file not found: {file_path}")
        post = frontmatter.load(file_path)
        return post

    def publish_medium(self, title: str, html_content: str, canonical_url: str, tags: List[str]) -> Optional[str]:
        """Dispatches canonical long-form post to Medium API."""
        if not self.medium_token or not self.medium_author_id:
            print("[!] Medium credentials missing; skipping Medium syndication.")
            return None

        url = f"https://api.medium.com/v1/users/{self.medium_author_id}/posts"
        headers = {
            "Authorization": f"Bearer {self.medium_token}",
            "Content-Type": "application/json",
            "Accept": "application/json"
        }
        payload = {
            "title": title,
            "contentFormat": "html",
            "content": html_content,
            "canonicalUrl": canonical_url,
            "tags": tags[:5],
            "publishStatus": "public"
        }
        res = requests.post(url, headers=headers, json=payload, timeout=15)
        if res.status_code == 201:
            data = res.json()
            post_id = data.get("data", {}).get("id")
            print(f"[✓] Medium Published Successfully: {post_id}")
            return post_id
        else:
            print(f"[!] Medium Error ({res.status_code}): {res.text}")
            return None

    def publish_linkedin(self, title: str, summary: str, canonical_url: str, tags: List[str]) -> Optional[str]:
        """Dispatches executive summary update to LinkedIn Share API."""
        if not self.linkedin_token or not self.linkedin_urn:
            print("[!] LinkedIn credentials missing; skipping LinkedIn syndication.")
            return None

        url = "https://api.linkedin.com/v2/ugcPosts"
        headers = {
            "Authorization": f"Bearer {self.linkedin_token}",
            "Content-Type": "application/json",
            "X-Restli-Protocol-Version": "2.0.0"
        }
        hashtags = " ".join([f"#{t}" for t in tags[:4]])
        share_comment = f"{title}\n\n{summary}\n\nRead the complete whitepaper below:\n{hashtags}"

        payload = {
            "author": self.linkedin_urn,
            "lifecycleState": "PUBLISHED",
            "specificContent": {
                "com.linkedin.ugc.ShareContent": {
                    "shareCommentary": {"text": share_comment},
                    "shareMediaCategory": "ARTICLE",
                    "media": [{
                        "status": "READY",
                        "originalUrl": canonical_url,
                        "title": {"text": title}
                    }]
                }
            },
            "visibility": {"com.linkedin.ugc.MemberNetworkVisibility": "PUBLIC"}
        }
        res = requests.post(url, headers=headers, json=payload, timeout=15)
        if res.status_code == 201:
            urn = res.headers.get("x-restli-id", "LINKEDIN_SUCCESS")
            print(f"[✓] LinkedIn Published Successfully: {urn}")
            return urn
        else:
            print(f"[!] LinkedIn Error ({res.status_code}): {res.text}")
            return None

    def chunk_twitter_thread(self, text: str, max_len: int = 260) -> List[str]:
        """Splits narrative into numbered tweets within character constraints."""
        paragraphs = [p.strip() for p in text.split("\n\n") if p.strip()]
        chunks = []
        for p in paragraphs:
            if len(p) <= max_len:
                chunks.append(p)
            else:
                # Sub-chunk by sentences
                sentences = re.split(r'(?<=[.!?]) +', p)
                current = ""
                for s in sentences:
                    if len(current) + len(s) + 1 <= max_len:
                        current = f"{current} {s}".strip()
                    else:
                        if current:
                            chunks.append(current)
                        current = s
                if current:
                    chunks.append(current)

        # Append thread pagination
        total = len(chunks)
        return [f"({i+1}/{total}) {c}" for i, c in enumerate(chunks)]

    def publish_twitter_thread(self, title: str, summary: str, canonical_url: str) -> Optional[str]:
        """Publishes sequentially chained Twitter/X thread."""
        if not self.twitter_client:
            print("[!] Twitter client not configured; skipping Twitter syndication.")
            return None

        thread_narrative = f"{title}\n\n{summary}\n\nCanonical Source: {canonical_url}"
        tweets = self.chunk_twitter_thread(thread_narrative)

        prev_tweet_id = None
        root_tweet_id = None

        for tweet_text in tweets:
            try:
                res = self.twitter_client.create_tweet(
                    text=tweet_text,
                    in_reply_to_tweet_id=prev_tweet_id
                )
                tweet_id = res.data["id"]
                if not root_tweet_id:
                    root_tweet_id = tweet_id
                prev_tweet_id = tweet_id
            except Exception as e:
                print(f"[!] Twitter Post Failure: {e}")
                break

        if root_tweet_id:
            print(f"[✓] Twitter Thread Dispatched: Root ID {root_tweet_id}")
        return root_tweet_id

    def syndicate_post(self, markdown_file: str):
        """End-to-End Orchestrator: Ingests markdown and syndicates to all channels."""
        post = self.parse_markdown(markdown_file)
        title = post.metadata.get("title", "Untitled Technical Dispatch")
        canonical_url = post.metadata.get("canonical_url", "https://bravoeconomy.com")
        summary = post.metadata.get("summary", title)
        tags = post.metadata.get("tags", ["Engineering", "FinTech", "Automation"])

        compiled_html = markdown.markdown(post.content)

        print(f"[*] Initiating Multi-Channel Syndication for: {title}")
        med_id = self.publish_medium(title, compiled_html, canonical_url, tags)
        li_id = self.publish_linkedin(title, summary, canonical_url, tags)
        tw_id = self.publish_twitter_thread(title, summary, canonical_url)

        # Record in local persistent ledger
        with sqlite3.connect(self.db_path) as conn:
            c = conn.cursor()
            c.execute("""
                INSERT OR REPLACE INTO publications
                (file_path, title, medium_post_id, linkedin_post_id, twitter_thread_root)
                VALUES (?, ?, ?, ?, ?)
            """, (markdown_file, title, med_id, li_id, tw_id))
            conn.commit()
        print("[✓] Syndication complete and persisted in audit database.")

if __name__ == "__main__":
    syndicator = OmniChannelSyndicator()
    print("[*] OmniChannelSyndicator Engine initialized and awaiting markdown payload.")
09. Production Hardening: API Rate Limit Backoff, Media Upload Retry & OAuth Refreshes
Distributing content through third-party platforms inevitably exposes your pipeline to external API volatility, temporary server downtime, and rate limits. The sovereign daemon enforces the following defensive mechanisms:
- Exponential Jitter Backoff: When a platform returns HTTP 429 (Too Many Requests), the client sleeps for $2^n \times \text{Uniform}(0.8, 1.2)$ seconds before retrying, avoiding stampeding herd locks.
- Image Upload Chunking with Checksums: Large infographics are pre-uploaded to platform media servers with chunked byte streams and validated against MD5 checksums before publication binding.
- Proactive Token Refresh Daemons: LinkedIn and Medium OAuth tokens are checked against local expiration timestamps; renewal flows are invoked 72 hours before expiration to prevent dispatch halts.
10. Sovereign Directive: Omnipresent Content Velocity Protocol
In the digital age, attention is the scarcest currency. Writing an institutional masterpiece and failing to distribute it across every modern channel is an act of intellectual negligence. The sovereign architect never relies on a single platform’s algorithmic benevolence.
By implementing the automated multi-channel syndication engine detailed in this laboratory, you enforce the following operational laws:
- Law of Single-Source Truth: Author your ideas once in a clean, portable master Markdown document; never duplicate writing effort inside proprietary web forms.
- Law of Canonical Attribution: Always enforce strict canonical URLs on external platforms (Medium, Substack) to concentrate search engine domain authority onto your self-hosted sovereign hub.
- Law of Format Optimization: Respect platform native cultures by compiling long-form HTML for research readers, concise bullet updates for professional networks, and atomic threaded insights for viral feeds.
- Law of Autonomous Omnipresence: Let software handle the labor of formatting, chunking, tagging, and API dispatching so your creative mind remains focused on high-alpha strategy.
Final Action Mandate: Connect your API keys, commit your master markdown drafts, execute the syndicator daemon, and command attention across the entire digital landscape on autopilot.


